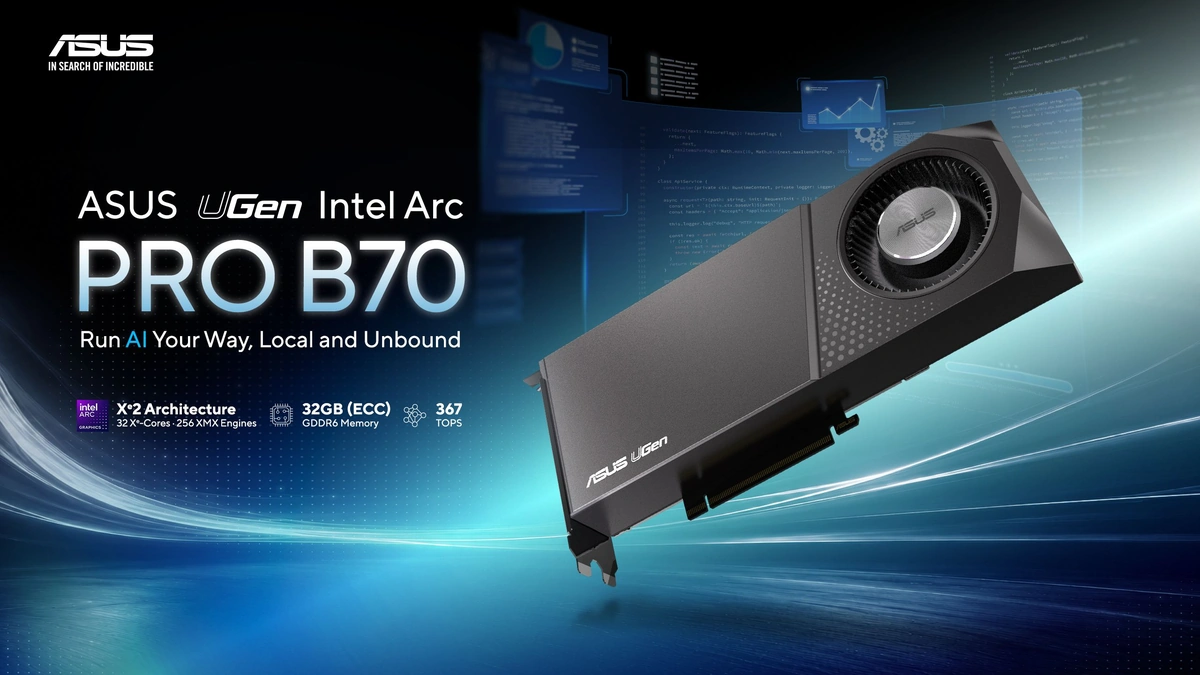
ASUS introduced the UGen Intel Arc Pro B70, a 32GB ECC GDDR6 graphics card for running language models locally on a desktop or workstation. A single UGen Intel Arc Pro B70 handles most models under 27 billion parameters, according to ASUS, and supports a context window of up to 128K tokens with Llama 3.1 8B. The card is rated at 310W.
ASUS says the memory size is the point. Long-context reasoning inflates KV-cache usage, multi-agent setups load several models at once, and when VRAM runs out the data moves to host memory, where inference performance can drop by up to 90%. ASUS compares the 32GB with the ceiling that mainstream 16GB cards put on larger models. Cards can be stacked: two give 64GB and four give 128GB, and ASUS reports that two-card configurations ran 80B-class models at 43.4 tokens per second.
The company's Agent Computer build guide shows where each count fits. One UGen Intel Arc Pro B70 sits in the AI development build next to the GeForce RTX 5090 32GB and Radeon AI PRO R9700 32GB, for 32B models at Q4 quantization. Two cards appear in the multi-GPU homelab build for models from 7B to 120B, and four in the enterprise workstation build. ASUS notes that supported model sizes vary with the GPU configuration and available memory. ASUS's release gives no price or ship date. PC Games Hardware reports a recommended price of €1,799 in Germany and Austria.
| Cards | VRAM | Build tier in ASUS's guide |
|---|---|---|
| 1 | 32GB | AI development build |
| 2 | 64GB | Multi-GPU homelab build |
| 4 | 128GB | Enterprise workstation |
ASUS lists the UGen Intel Arc Pro B70 as supported by Intel LLM Scaler and vLLM XPU, llama.cpp through SYCL and Vulkan, Ollama, OpenVINO, oneAPI, PyTorch XPU and ComfyUI for image generation. The verified model list spans Llama 3.1 and 3.2 models from 8B to 70B, Qwen 3.x models, DeepSeek-R1 Distill, Mistral and Mixtral, gpt-oss in 20B and 120B sizes, Whisper-large-v3 and InternVL3.5. LLM Scaler also quantizes to INT4 or FP8 on the fly, which ASUS says removes the dependency on external CUDA-based quantization tools.