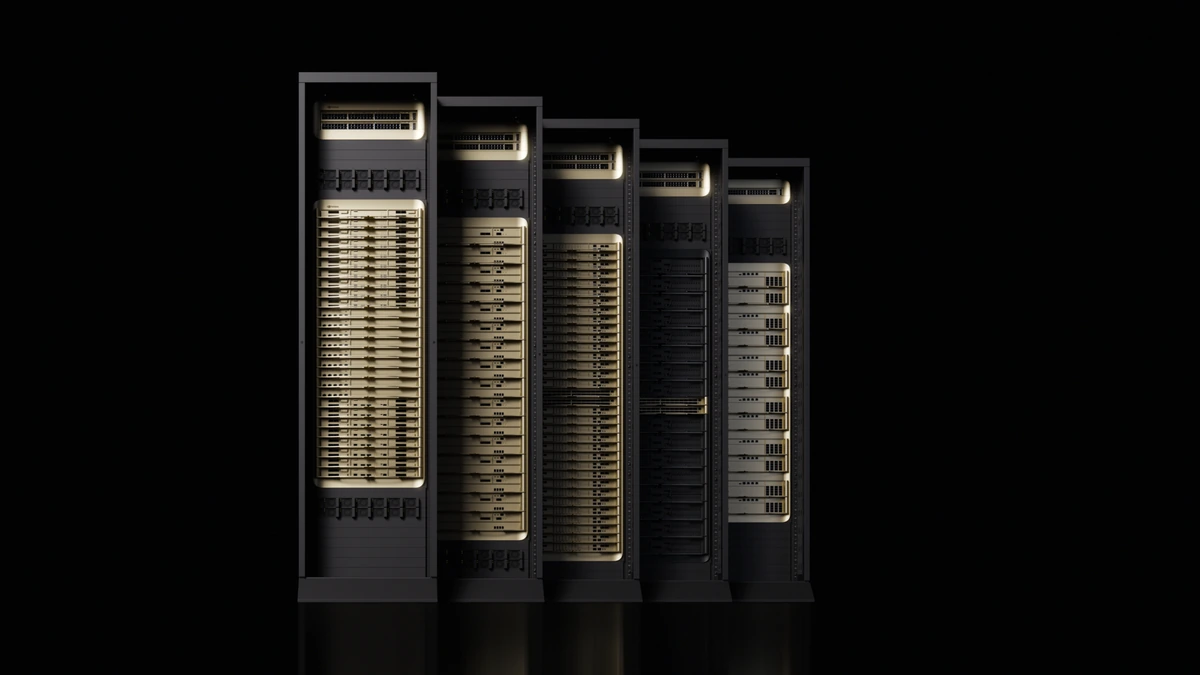
NVIDIA Puts Groq 3 LPX into Production to Cut Agent Decode Latency
NVIDIA's Groq 3 LPX inference system is in full production, extending Vera Rubin NVL72 with fast token generation for agentic AI.
By Kenji Sato
The engineering behind shipping AI: MLOps and LLMOps pipelines, model training and fine-tuning, feature stores, inference serving, and the platforms such as Amazon SageMaker and Vertex AI that move models from notebook to production.
NVIDIA's Groq 3 LPX inference system is in full production, extending Vera Rubin NVL72 with fast token generation for agentic AI.
By Kenji Sato
Julian Beaumont
Julian Beaumont