Amazon SageMaker AI is a managed machine learning service that AWS now says requires monitoring across two distinct but interdependent dimensions, infrastructure quantity and response quality, to operate production LLM inference reliably, according to AWS.
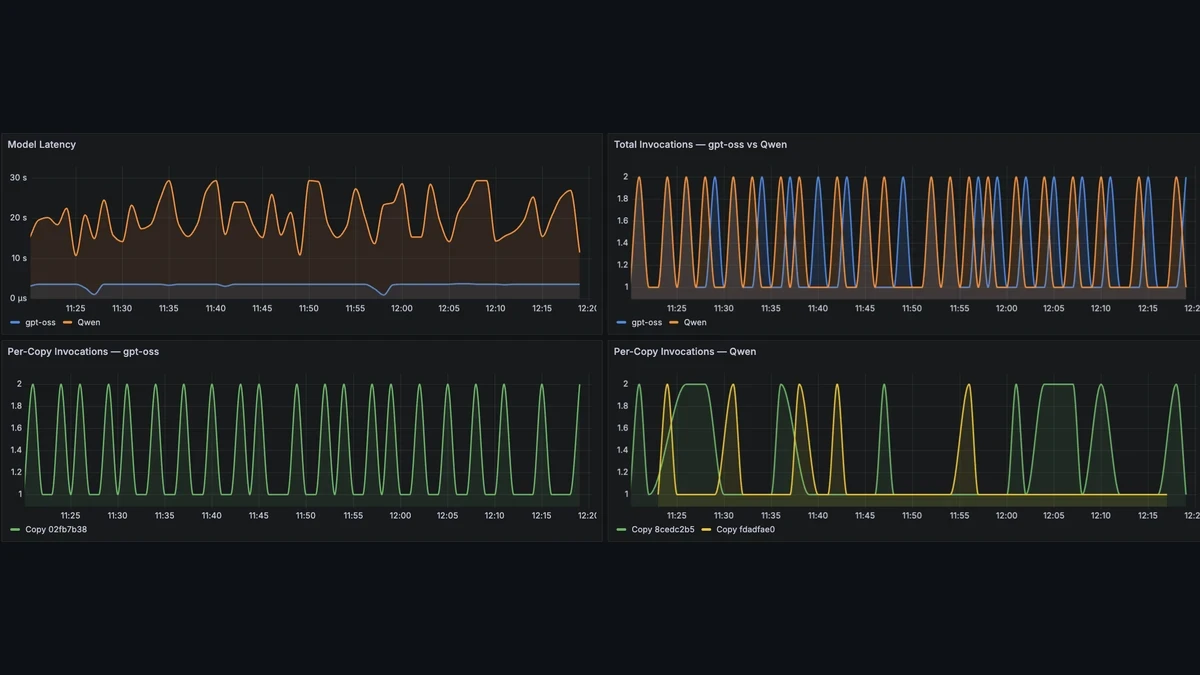
The AWS post, authored by Amazon SageMaker AI solutions architects Sandeep Raveesh-Babu and Jonathan Kola, describes a two-dashboard observability solution built on Amazon SageMaker AI inference components, Amazon CloudWatch, and Amazon Managed Grafana. The quantity-focused Grafana dashboard tracks GPU compute and memory utilization per inference component, model invocation counts, request latency, and per-model hourly cost. A separate quality dashboard tracks LLM-as-judge metrics including composite quality scores, safety scores, and relevance scores over time, with configurable alert thresholds delivered via Amazon SNS to channels such as Slack, PagerDuty, or OpsGenie.
The architectural distinction matters because the two failure modes are invisible to each other. An Amazon SageMaker AI endpoint can appear operationally healthy on CloudWatch metrics while silently degrading on output quality; conversely, a model delivering high-quality responses can run on grossly over-provisioned GPU infrastructure, driving unnecessary cost. AWS says neither Amazon CloudWatch enhanced metrics nor custom quality metrics surfaced in Grafana Alerting can substitute for the other; production readiness requires both data streams correlated in the same Amazon Managed Grafana workspace.
The quality evaluation pipeline in the proposed solution uses an LLM-as-judge pattern. AWS specifies Anthropic Claude Sonnet 4.6 served through Amazon Bedrock as the evaluator model, scoring Amazon SageMaker AI inference outputs against configurable rubrics for relevance, safety, and professional tone. Teams substituting a different evaluator model need to verify that the model's terms permit evaluating third-party outputs and pin the evaluator to a specific version so quality scores remain comparable across model updates.
AWS publishes sample notebooks for the full solution in its public samples GitHub repository, covering enhanced metric configuration, custom quality metric publishing, and the Grafana dashboard definitions. The observability pattern is not Amazon SageMaker AI-specific in its reasoning: any team running multiple LLMs on shared GPU infrastructure faces the same gap between operational health and output quality, and the same architecture translates to other managed inference services with compatible CloudWatch metric namespaces.